Slack AI Assistant
An enterprise-grade multimodal n8n automation engine integrating dual-model intelligence, voice-to-text processing, and fail-safe error handling for real-time Slack operations.
Automation System & Workflows
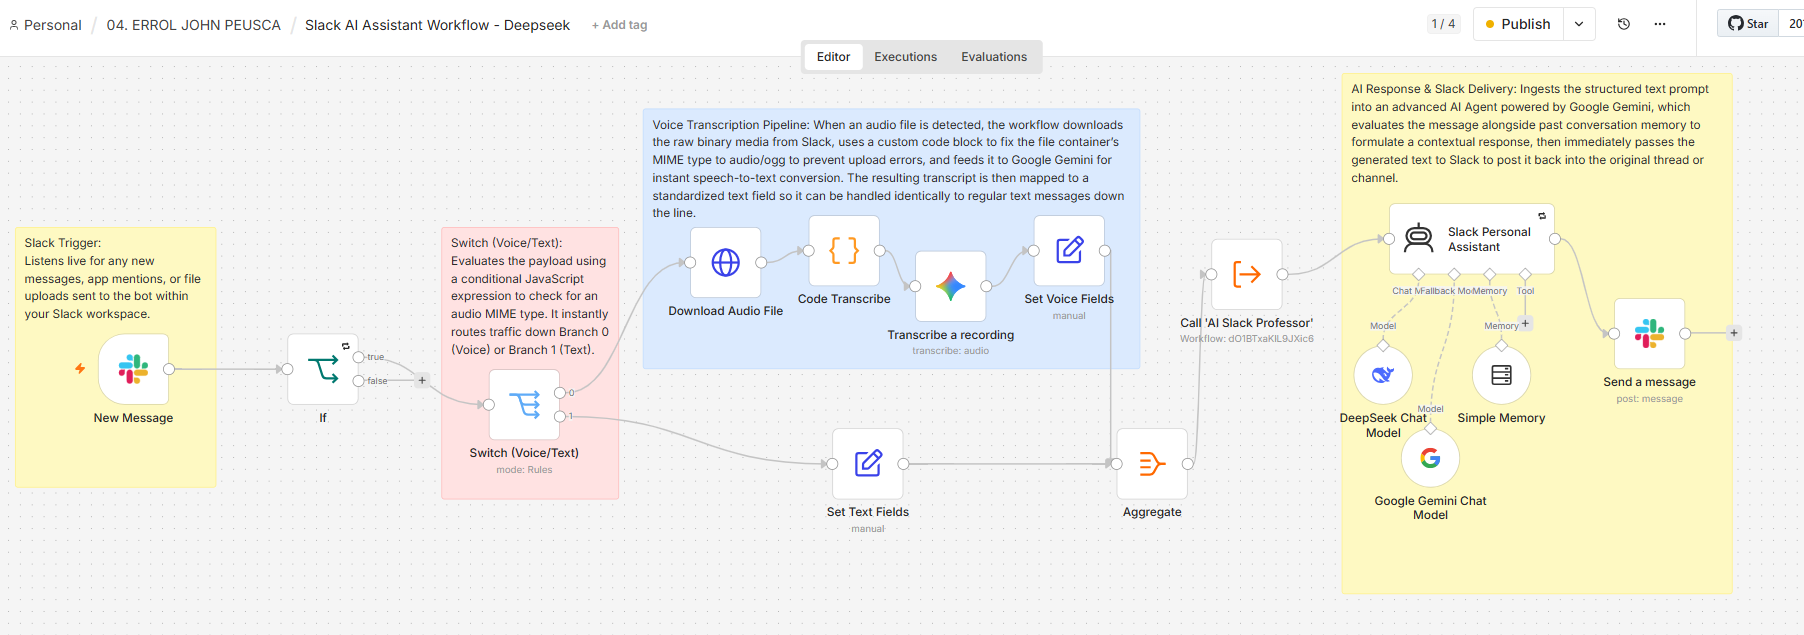
End-to-end multimodal production canvas routing Slack events through audio normalization, speech-to-text transcription, and dual-model AI agent nodes.
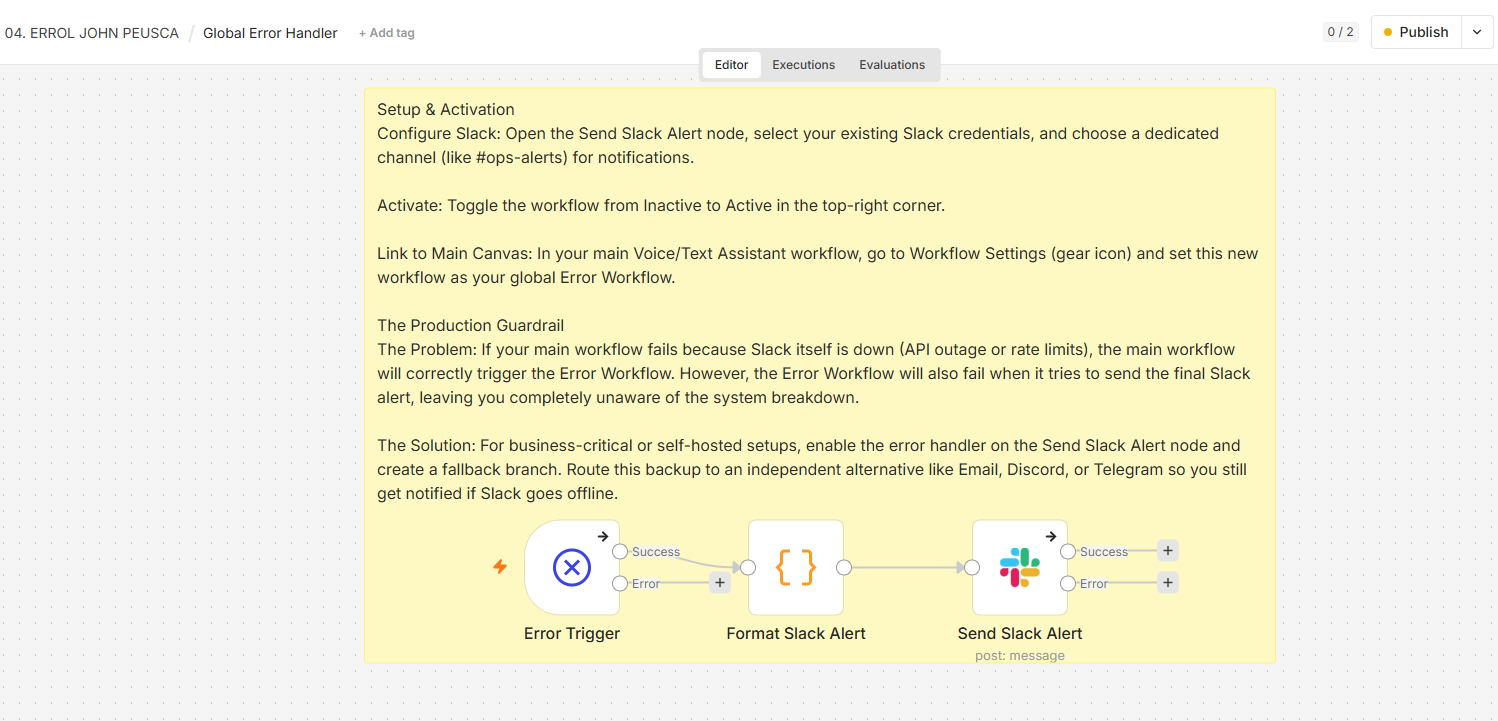
Decoupled fail-safe error monitoring pipeline that intercepts runtime exceptions and dispatches actionable incident cards to fallback channels.
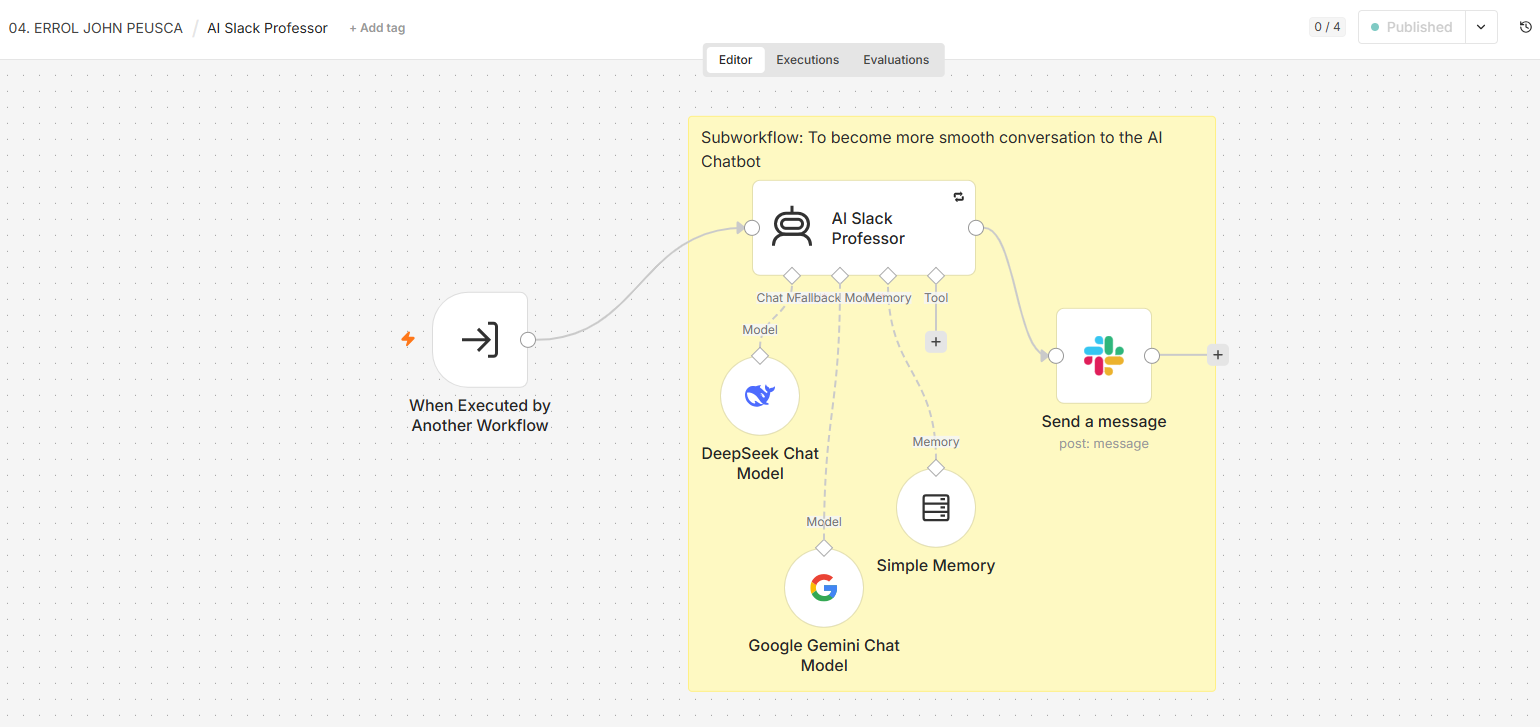
Modular conversational subworkflow orchestrating DeepSeek reasoning with Google Gemini fallback and conversation window buffer memory.
Case Study Breakdown
Introduction
Slack AI Personal Assistant — Multi-Modal Business Communication Engine
Operations and support teams lose critical hours manually triaging high volumes of Slack messages, inquiries, and audio memos, causing response delays, inconsistent communication, and team burnout.
The Challenges
- Voice Note & Triage Bottleneck: Incoming audio memos forced staff to pause work, listen in real time, and manually transcribe action items, leading to response delays of 15 to 45 minutes.
- Loss of Context & Inconsistent Quality: Manual replies depended entirely on individual staff memory and shift handoffs, causing lost conversation history and conflicting answers.
- Single-API Vulnerability & Silent Outages: Relying on a single AI model left workflows exposed to third-party rate limits and outages, where broken automations failed quietly without alerting the team.
The Solution
Engineered an enterprise-grade, multimodal AI automation ecosystem inside n8n with dual-model redundancy, speech-to-text processing, and decoupled fail-safe monitoring:
- Multimodal Ingestion & Audio Normalization: Routes incoming text, mentions, and audio files automatically, utilizing a custom JavaScript container fix to prepare voice memos for instant transcription via Google Gemini STT.
- Dual-Model AI Engine & Context Memory: Orchestrates DeepSeek V3/R1 as the primary reasoning engine with automatic, sub-second failover to Google Gemini 1.5, backed by window buffer memory for continuous multi-turn conversations.
- Decoupled Global Error Handler: Catches unexpected runtime failures across all nodes, translating raw error logs into clear, actionable incident cards sent to backup channels like Email or Discord.
The Results
- 98% Faster Response Times: Reduced average response latency from 15–45 minutes down to under 45 seconds, delivering reliable 24/7 assistance across time zones.
- 100% Labor Reclaimed: Fully automated voice note transcription and routine inquiries, freeing team members to focus on strategic operations and client management.
- Zero-Downtime Reliability: Eliminated communication blind spots with dual-model redundancy and automated out-of-band incident alerts, preventing silent system failures.
Replaced manual triage with an enterprise-grade multimodal AI engine, slashing response latency by 98% down to sub-45s with zero-downtime dual-model reliability.